
Building Blocks for Foundation Model Training and Inference on AWS
AI Summary
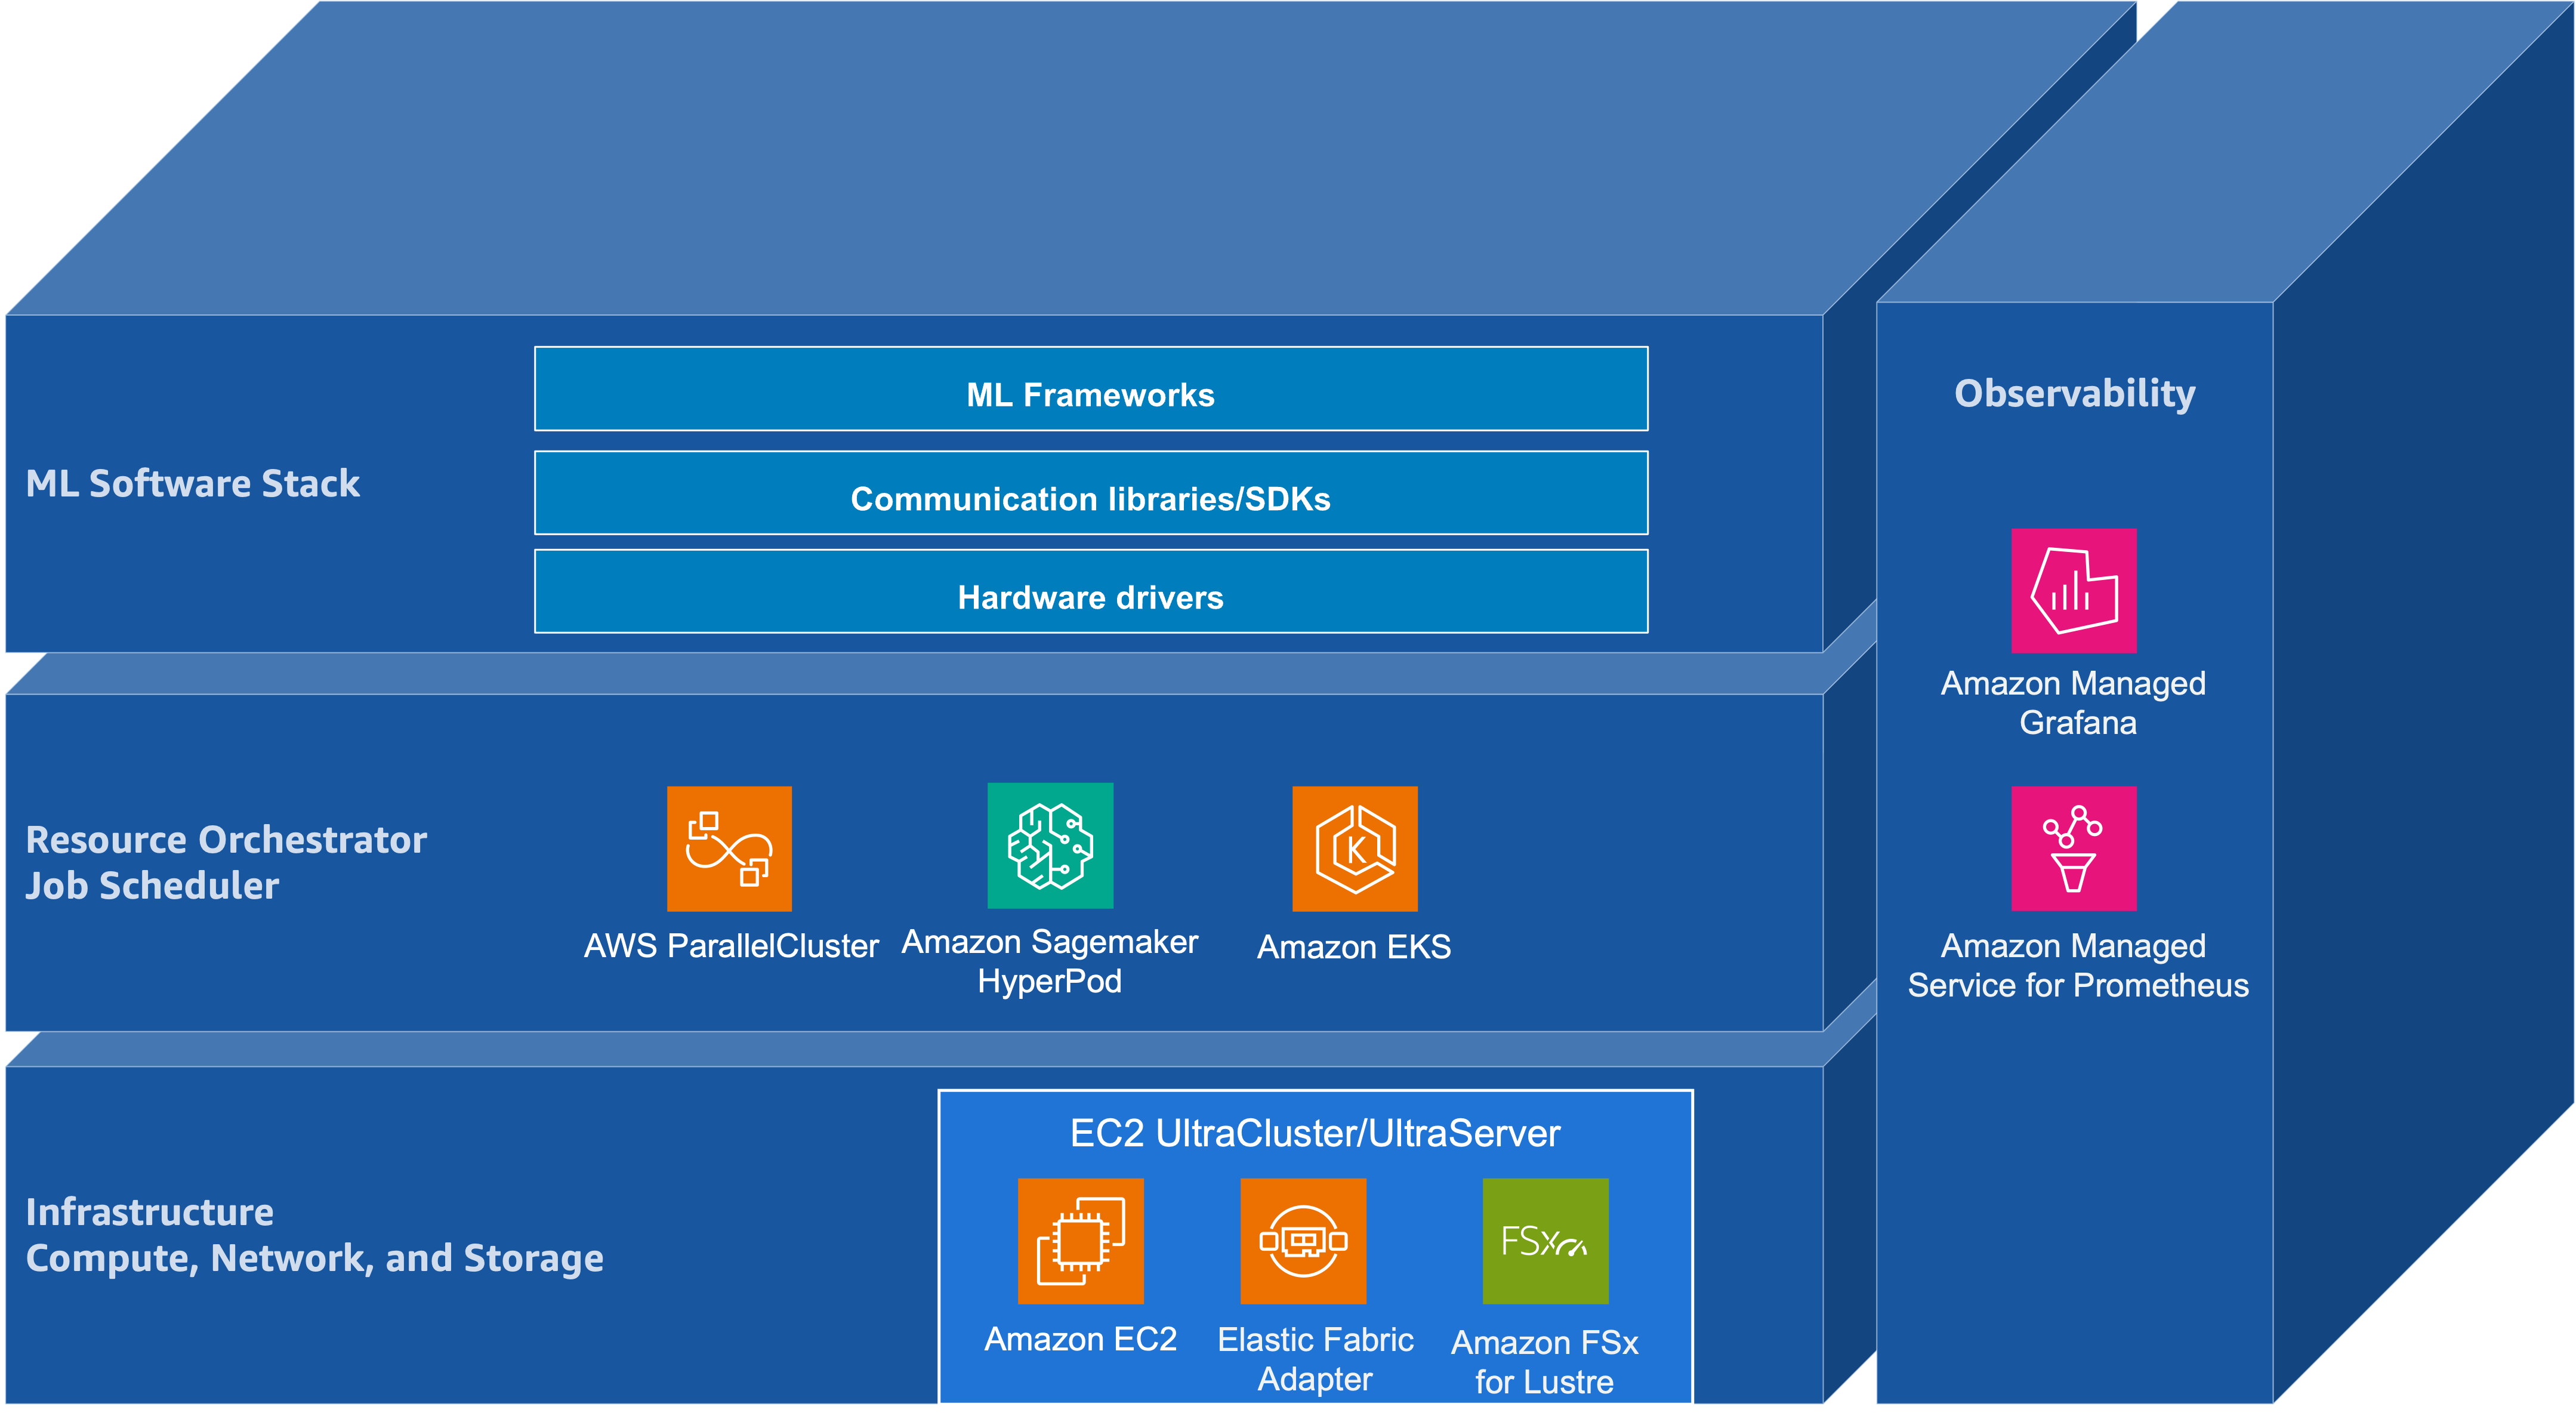
This article explores the foundational infrastructure, open-source software (OSS) stacks, and orchestration frameworks required for training and running inference on large foundation models. It details how AWS infrastructure components—such as Amazon EC2, Elastic Fabric Adapter (EFA), and SageMaker HyperPod—integrate with tools like Slurm, Kubernetes, PyTorch, and Prometheus to address bottlenecks in pre-training, post-training, and inference workflows.
Key Takeaways
- Modern foundation model scaling spans pre-training, post-training, and test-time compute, creating convergent infrastructure needs for compute, network, and storage.
- AWS provides key hardware and networking blocks like EC2 instances and EFA for OS-bypass RDMA communication to accelerate distributed training.
- Orchestration tools like Slurm and Amazon EKS (via SageMaker HyperPod) manage cluster resources, though they differ in job-level atomicity and scheduling semantics.
Why it matters
Understanding how cloud infrastructure interacts with open-source machine learning stacks is essential for ML and systems engineers to optimize distributed training performance, manage cluster resource allocation, and diagnose scaling bottlenecks at scale.
Conversation 0
Be the first to share your perspective.