
Inkling 2 Small, GLM-5.5 Pipeline, and SSD MoE Inference Updates
AI Summary
This article discusses recent developments in open-weight models and inference systems, including Inkling 2 Small, the upcoming GLM-5.5 training pipeline, and llama.cpp-based Mixture-of-Experts (MoE) streaming from SSDs. It also touches on agent-tuned serving metrics and practical experiences with autonomous coding tools like Codex versus Claude Code.
Key Takeaways
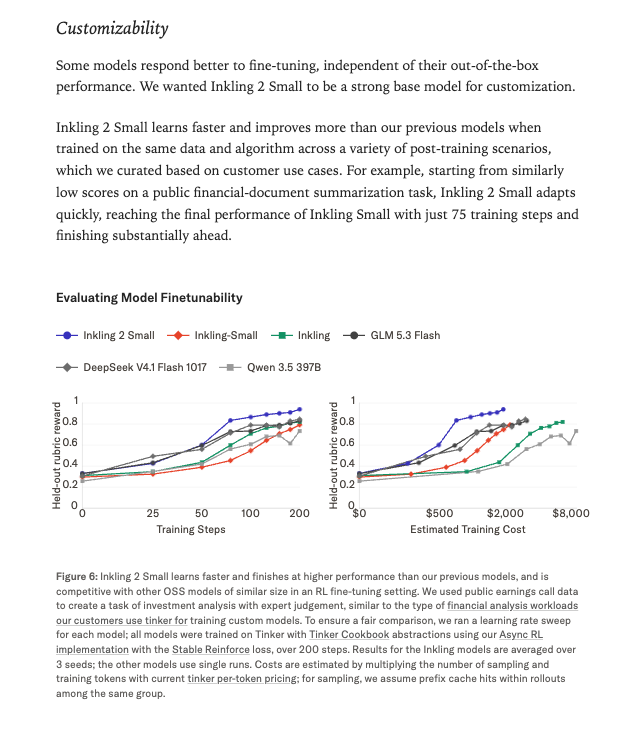
- Inkling 2 Small features customizability and competitive performance among open-weight models.
- An SSD-based MoE inference engine approach can offload 60 to 70 percent of routed experts to storage with minimal streaming overhead.
- Comparative developer experiences highlight significant tradeoffs between autonomous coding assistants like Codex and Claude Code.
Why it matters
Understanding advancements in efficient model pretraining, hardware offloading for MoE inference, and agentic serving strategies helps engineers optimize local and cloud deployments under strict resource constraints.
Conversation 0
Be the first to share your perspective.