
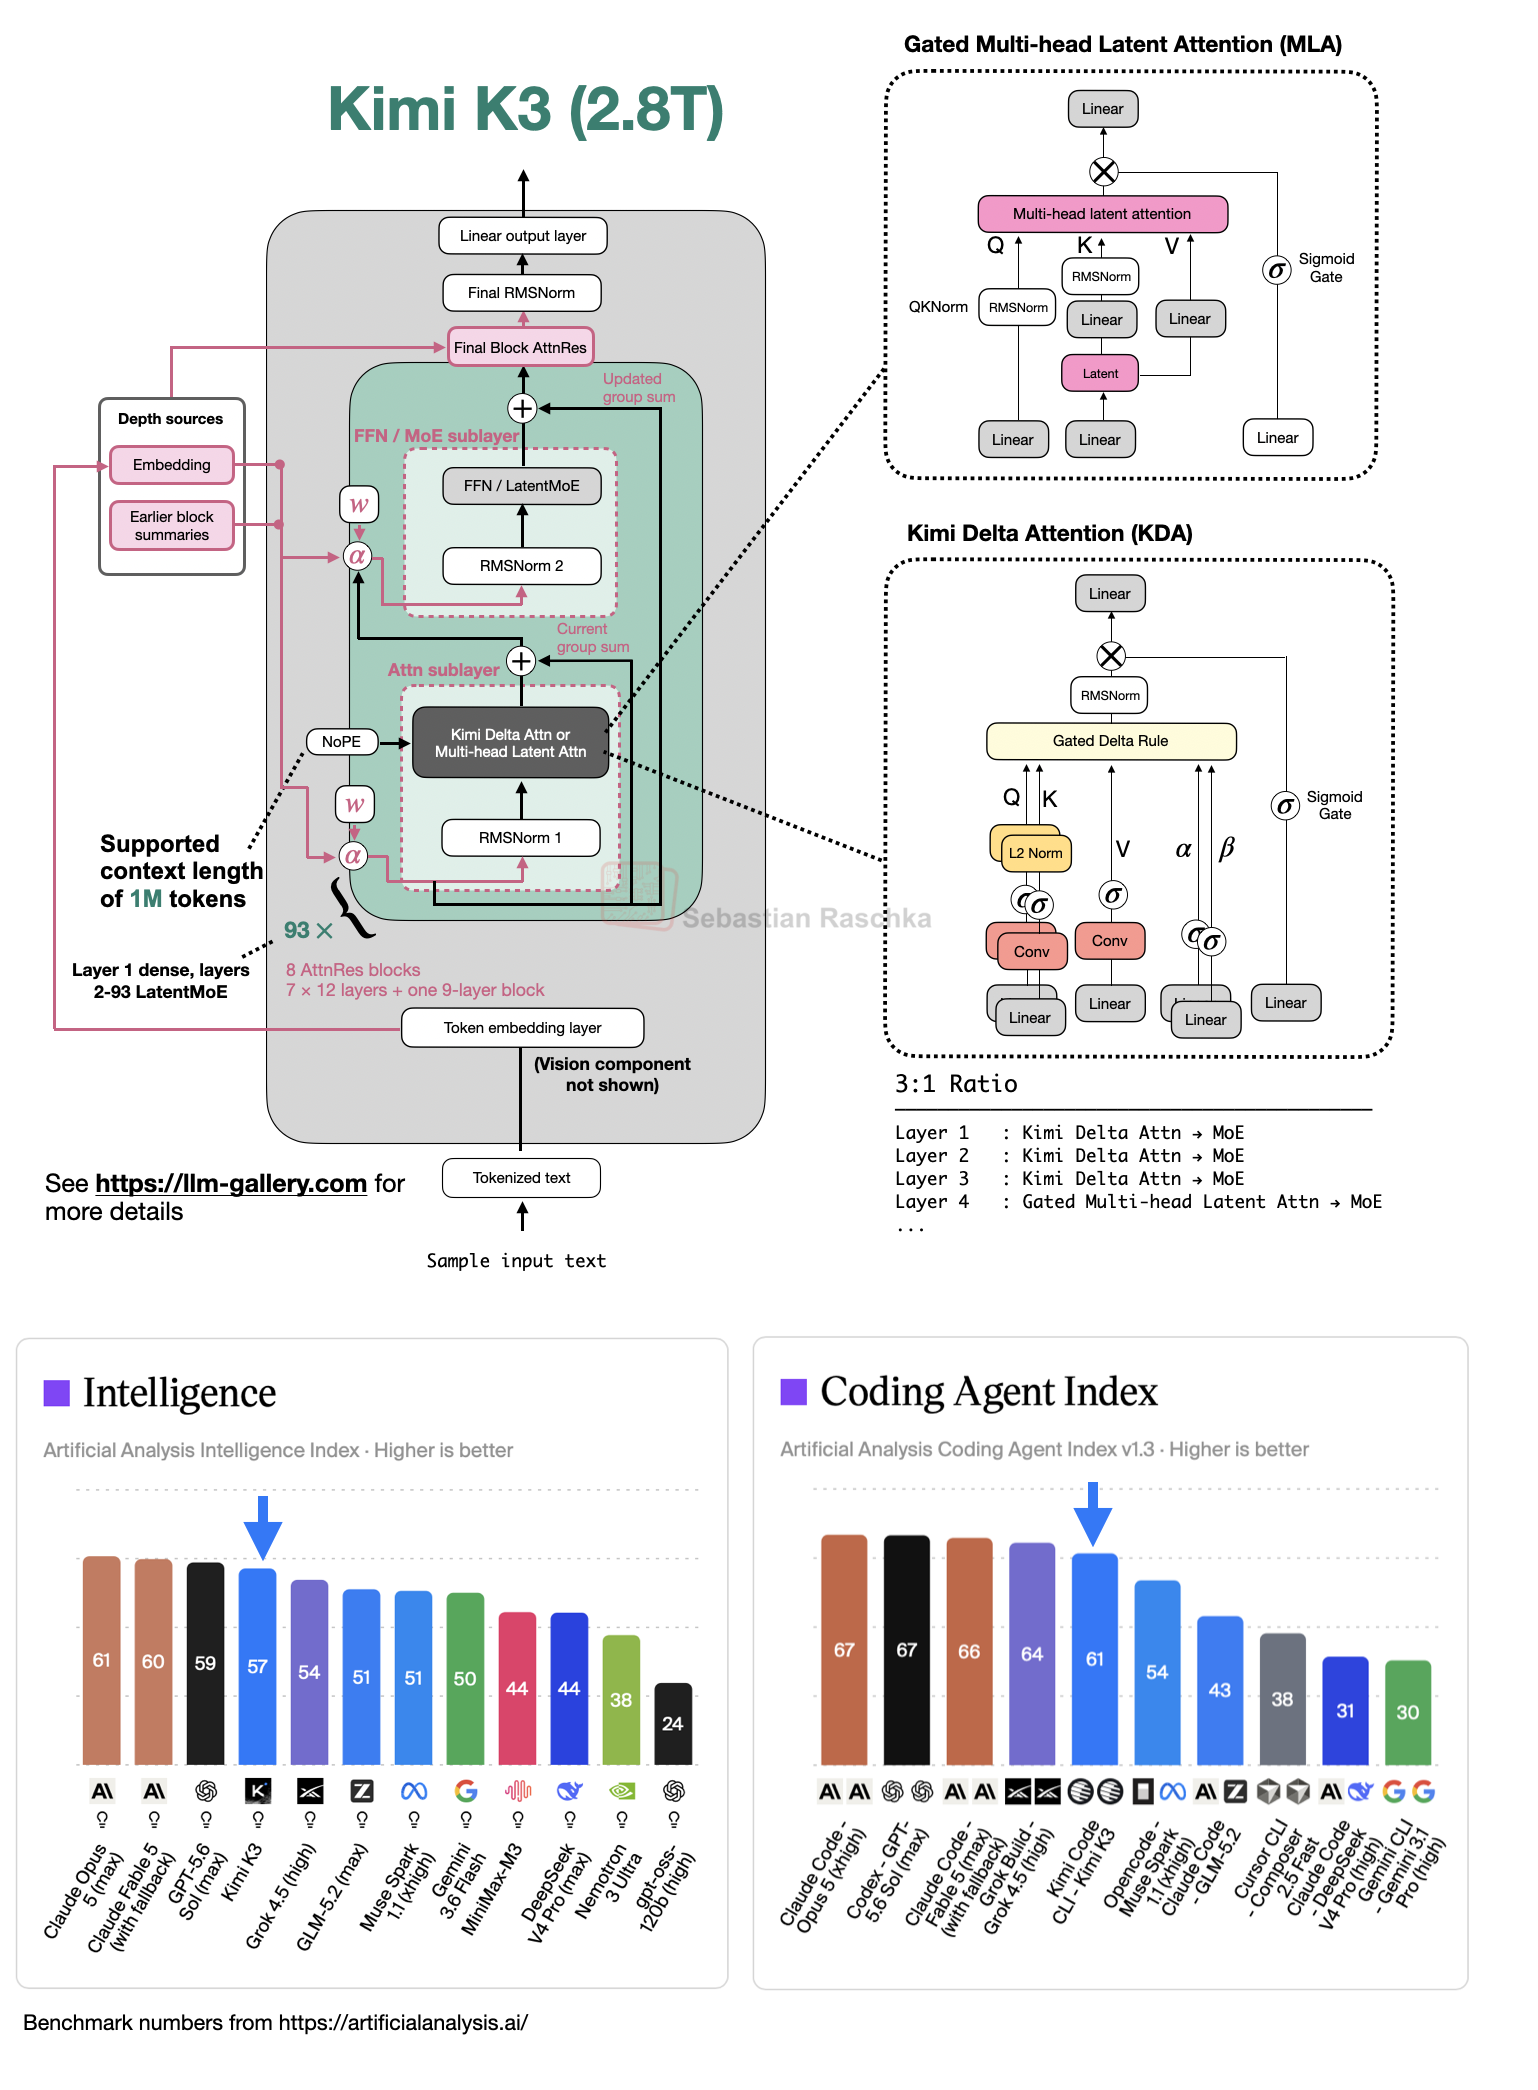
Kimi K3 Architecture Notes
AI Summary
An architectural breakdown of the Kimi K3 open-weight model, scaled up from the Kimi Linear model to 2.8 trillion parameters. It introduces LatentMoE for compressing large linear layers, utilizes attention residuals to connect residuals across layers using attention scores, and entirely removes RoPE layers in favor of NoPE (No Positional Embeddings) globally. The model also features native multimodal support and focuses heavily on inference efficiency.
Key Takeaways
- Scaled up from the Kimi Linear model from 48B to 2.8T parameters.
- Replaces standard components with efficiency-tweaked versions such as LatentMoE, multi-head latent attention, and Kimi Delta Attention.
- Removes RoPE layers entirely, utilizing NoPE (No Positional Embeddings) across the entire architecture.
Why it matters
Understanding the architectural decisions behind a massive 2.8T open-weight model like Kimi K3 provides valuable insights into current industry trends focusing on inference efficiency, alternative positional embeddings (NoPE), and advanced residual connections.
Conversation 0
Be the first to share your perspective.